Technical
The Real Cost of a Render: FinOps for a Generative Studio
· RenderBob team
In 2026 a generative studio pays for compute in three fundamentally different currencies at once, and confusing them is how render costs quietly get out of control.
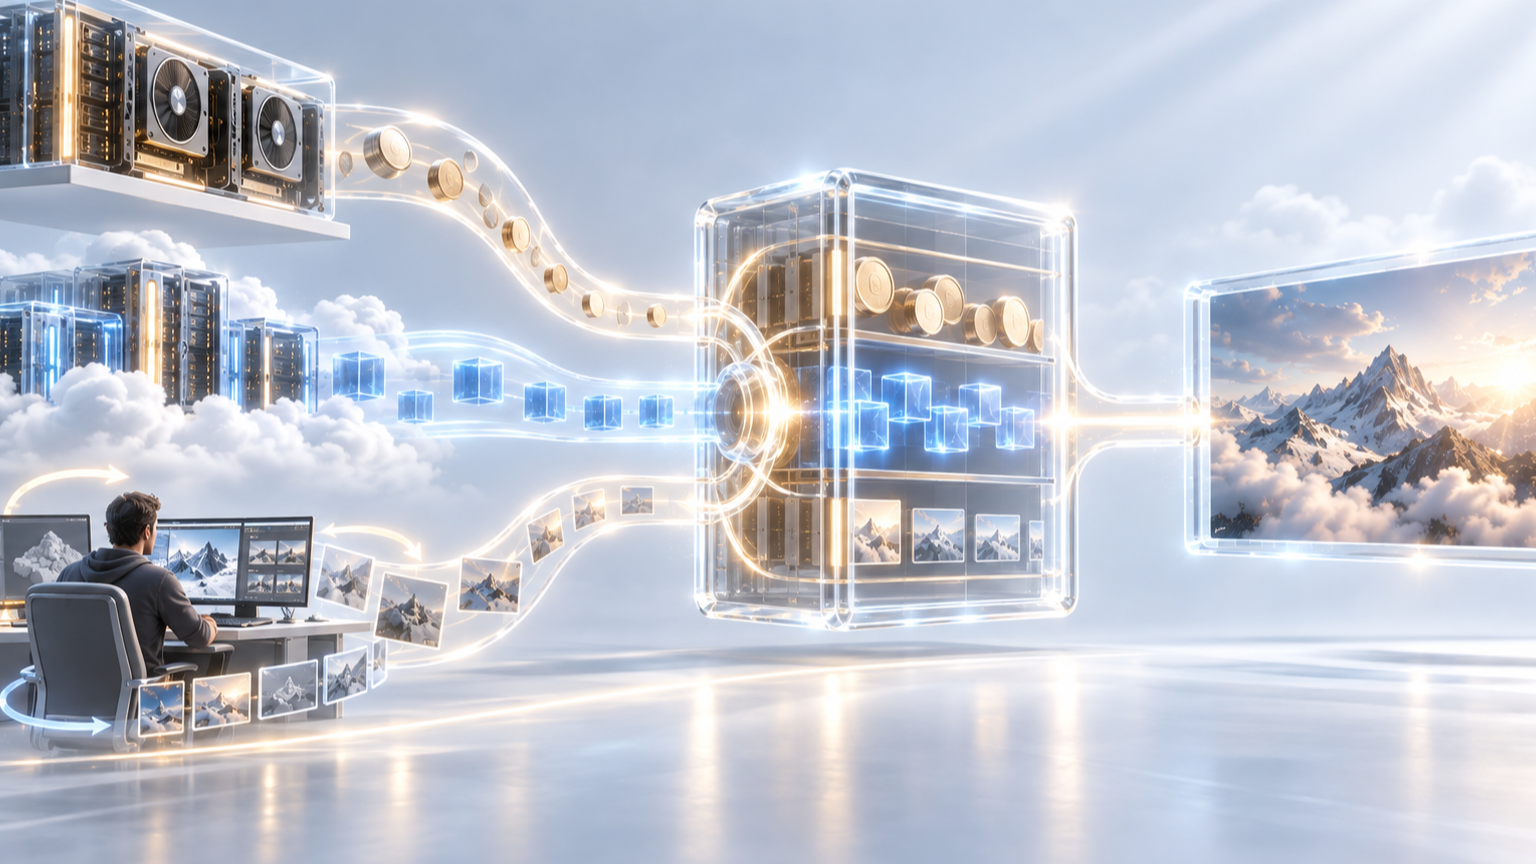
In 2026 a generative studio pays for compute in three fundamentally different currencies at once, and confusing them is how render costs quietly get out of control. Understanding the three is the start of running a studio like a business rather than a hobby with invoices.
Owned hardware is capex
You pay once, up front, and the marginal cost of a render is basically electricity. It is the cheapest way to serve steady, predictable baseline load, but in 2026 the up-front cost is high and the hardware is scarce, and idle capacity is money sitting still. Owned compute rewards high, consistent utilisation and punishes buying for a peak you hit twice a year.
Cloud GPU is opex, and it has sub-flavours that matter
On-demand instances cost the most but are always available. Reserved capacity is cheaper for predictable baseline. Spot or interruptible instances are cheapest of all, often dramatically so, but can be reclaimed mid-job, which is fine for restartable, checkpointed batch work and dangerous for a single long render with no save points. Matching the instance type to the job's interruptibility is real money.
Partner-node API models are per-call credits
A frontier model called from a node bills per second or per image. MiniMax's own API bills $0.13 a second at 2K ($0.08 at 768p); Nano Banana Pro has its own per-image rate. There is no provisioning and no idle cost, but there is no volume discount from owning the hardware either. Per-call is cheap for occasional frontier passes and expensive as a default for high-volume work.
Put those together and the cost-optimal pipeline is a deliberate mix, not all owned or all cloud. Steady, high-volume rendering on owned hardware where the marginal cost is near zero. Peak overflow on spot or on-demand cloud that exists only while the job runs. Specific frontier passes on per-call API models where the capability is worth the credits. The mistake is picking one currency and forcing every job into it: pay per-call for your bulk rendering and the bill balloons; buy owned hardware for a rare peak and it sits idle.
None of this is manageable by feel. FinOps for a generative studio needs the same guardrails good cloud teams use: hard caps and budget alarms, automatic idle shutdown, and cost per frame, measured consistently across owned, cloud and API compute. Without cost-per-frame, you cannot see which jobs are cheap where, and every routing decision is a guess.
That measurement and routing is what a control plane provides. Deciding which currency each job pays in, enforcing the caps, shutting down idle nodes, and reporting cost per frame across the whole mixed fleet is FinOps in practice, and it is the difference between a studio that knows what a render costs and one that finds out at the end of the month.
More from the blog
- Human Authorship Is Becoming the Unit of Value
The Oscars' 2026 AI rules, Cannes' unpublished competition stance, a patchwork of festival policies, and the Thaler copyright denial all ask how much of a film a human authored.
- Ideation Is the Green Zone: Where Studios Allow AI and Where They Stop
Netflix's generative AI guidance for production partners treats concept work as the open case and final deliverables as the restricted one. That split is spreading as a working template.