Workflow
An AI-Augmented Motion Graphics Pipeline: C4D to ComfyUI and Back
· RenderBob team
The most interesting motion work in 2026 blends classical layout and control from tools like Cinema 4D with generative texture, style and video passes from ComfyUI, then composites them back together.
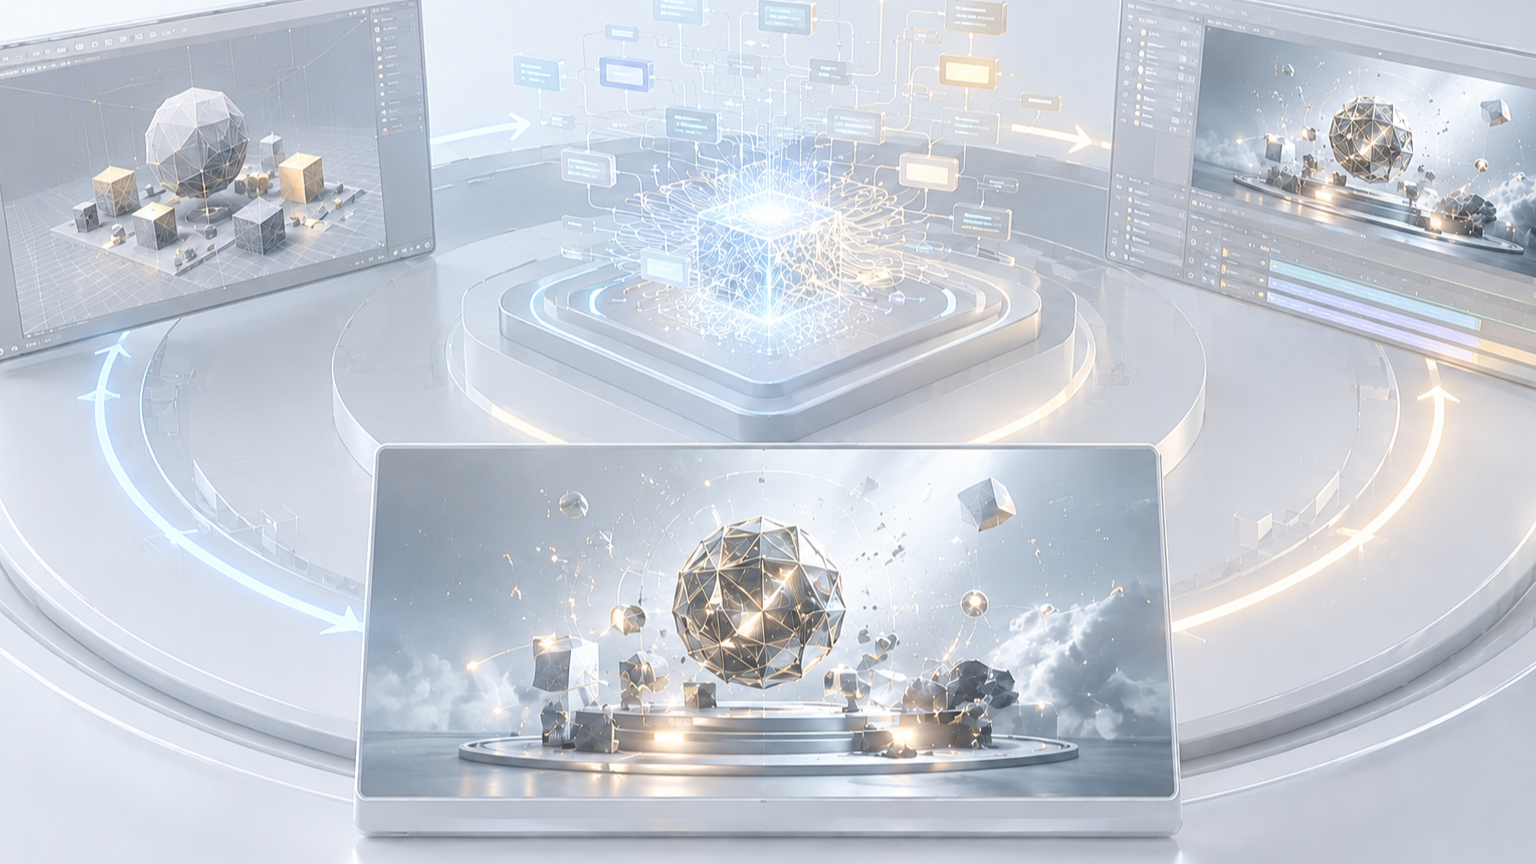
A lot of the interesting motion work in 2026 is a blend: traditional layout and control from tools like Cinema 4D, generative texture, style and video passes from ComfyUI, composited back together. The pipeline flows in four stages, and the hardware decisions live at each one.
Stage 1: Layout and control (classical, local)
The shot is blocked out in the DCC: camera, timing, rough geometry, and the control passes (depth, normals, mattes) that will guide the generative step. This stage is CPU/GPU-modest and lives comfortably on owned workstations.
Stage 2: Generative pass (ComfyUI)
The control passes drive a ComfyUI workflow: a video model (Wan, LTX, or similar) conditioned on the depth and mattes so the generated motion respects the layout. This is the VRAM-hungry stage. Iteration and preview versions run on owned nodes; the final full-resolution, full-length pass is the one that OOMs locally and belongs on a right-sized node.
Stage 3: Upscale and finish (ComfyUI)
A separate upscale pass (the stage where LTX-style workflows famously spike VRAM) lifts the result to delivery resolution. Splitting this from Stage 2, save latents, run upscale separately, avoids the memory spike where both stages coexist.
Stage 4: Composite and grade (classical, local)
The generative output comes home to be composited with classical elements, graded, and finished. Back on owned workstations, where this work has always lived.
Generative stages are separable and burstable. Classical stages are steady and local. Stages 1 and 4 never need to leave owned hardware. Stage 2's final pass and Stage 3 are the jobs worth routing to elastic capacity when they exceed local VRAM or when the queue is full during a delivery window.
For this to feel like one pipeline rather than a relay race, three things have to hold. The ComfyUI environment must be reproducible, so the generative pass produces the same result wherever it runs. The submission must be unified, so an artist sends the heavy pass the same way they send a preview. And deployment must be abstracted, so "run this on a cloud node" is a routing decision, not a workflow rebuild.
More from the blog
- Two Lanes of AI Editing: Mechanical Cleanup and Narrative Assembly
AI editing tools split into cleanup that follows story decisions and assembly that proposes them. A third question, local or cloud processing, now cuts across both.
- "Just Regenerate": The Bad-Seed Workaround Culture in AI Video Editing
While reference-guided video stays unreliable, working practice is blunt: do not commit a clip until you have looked, delete a stuck result, and switch models when one keeps missing.